Can AI automate AI R&D yet?
Summary
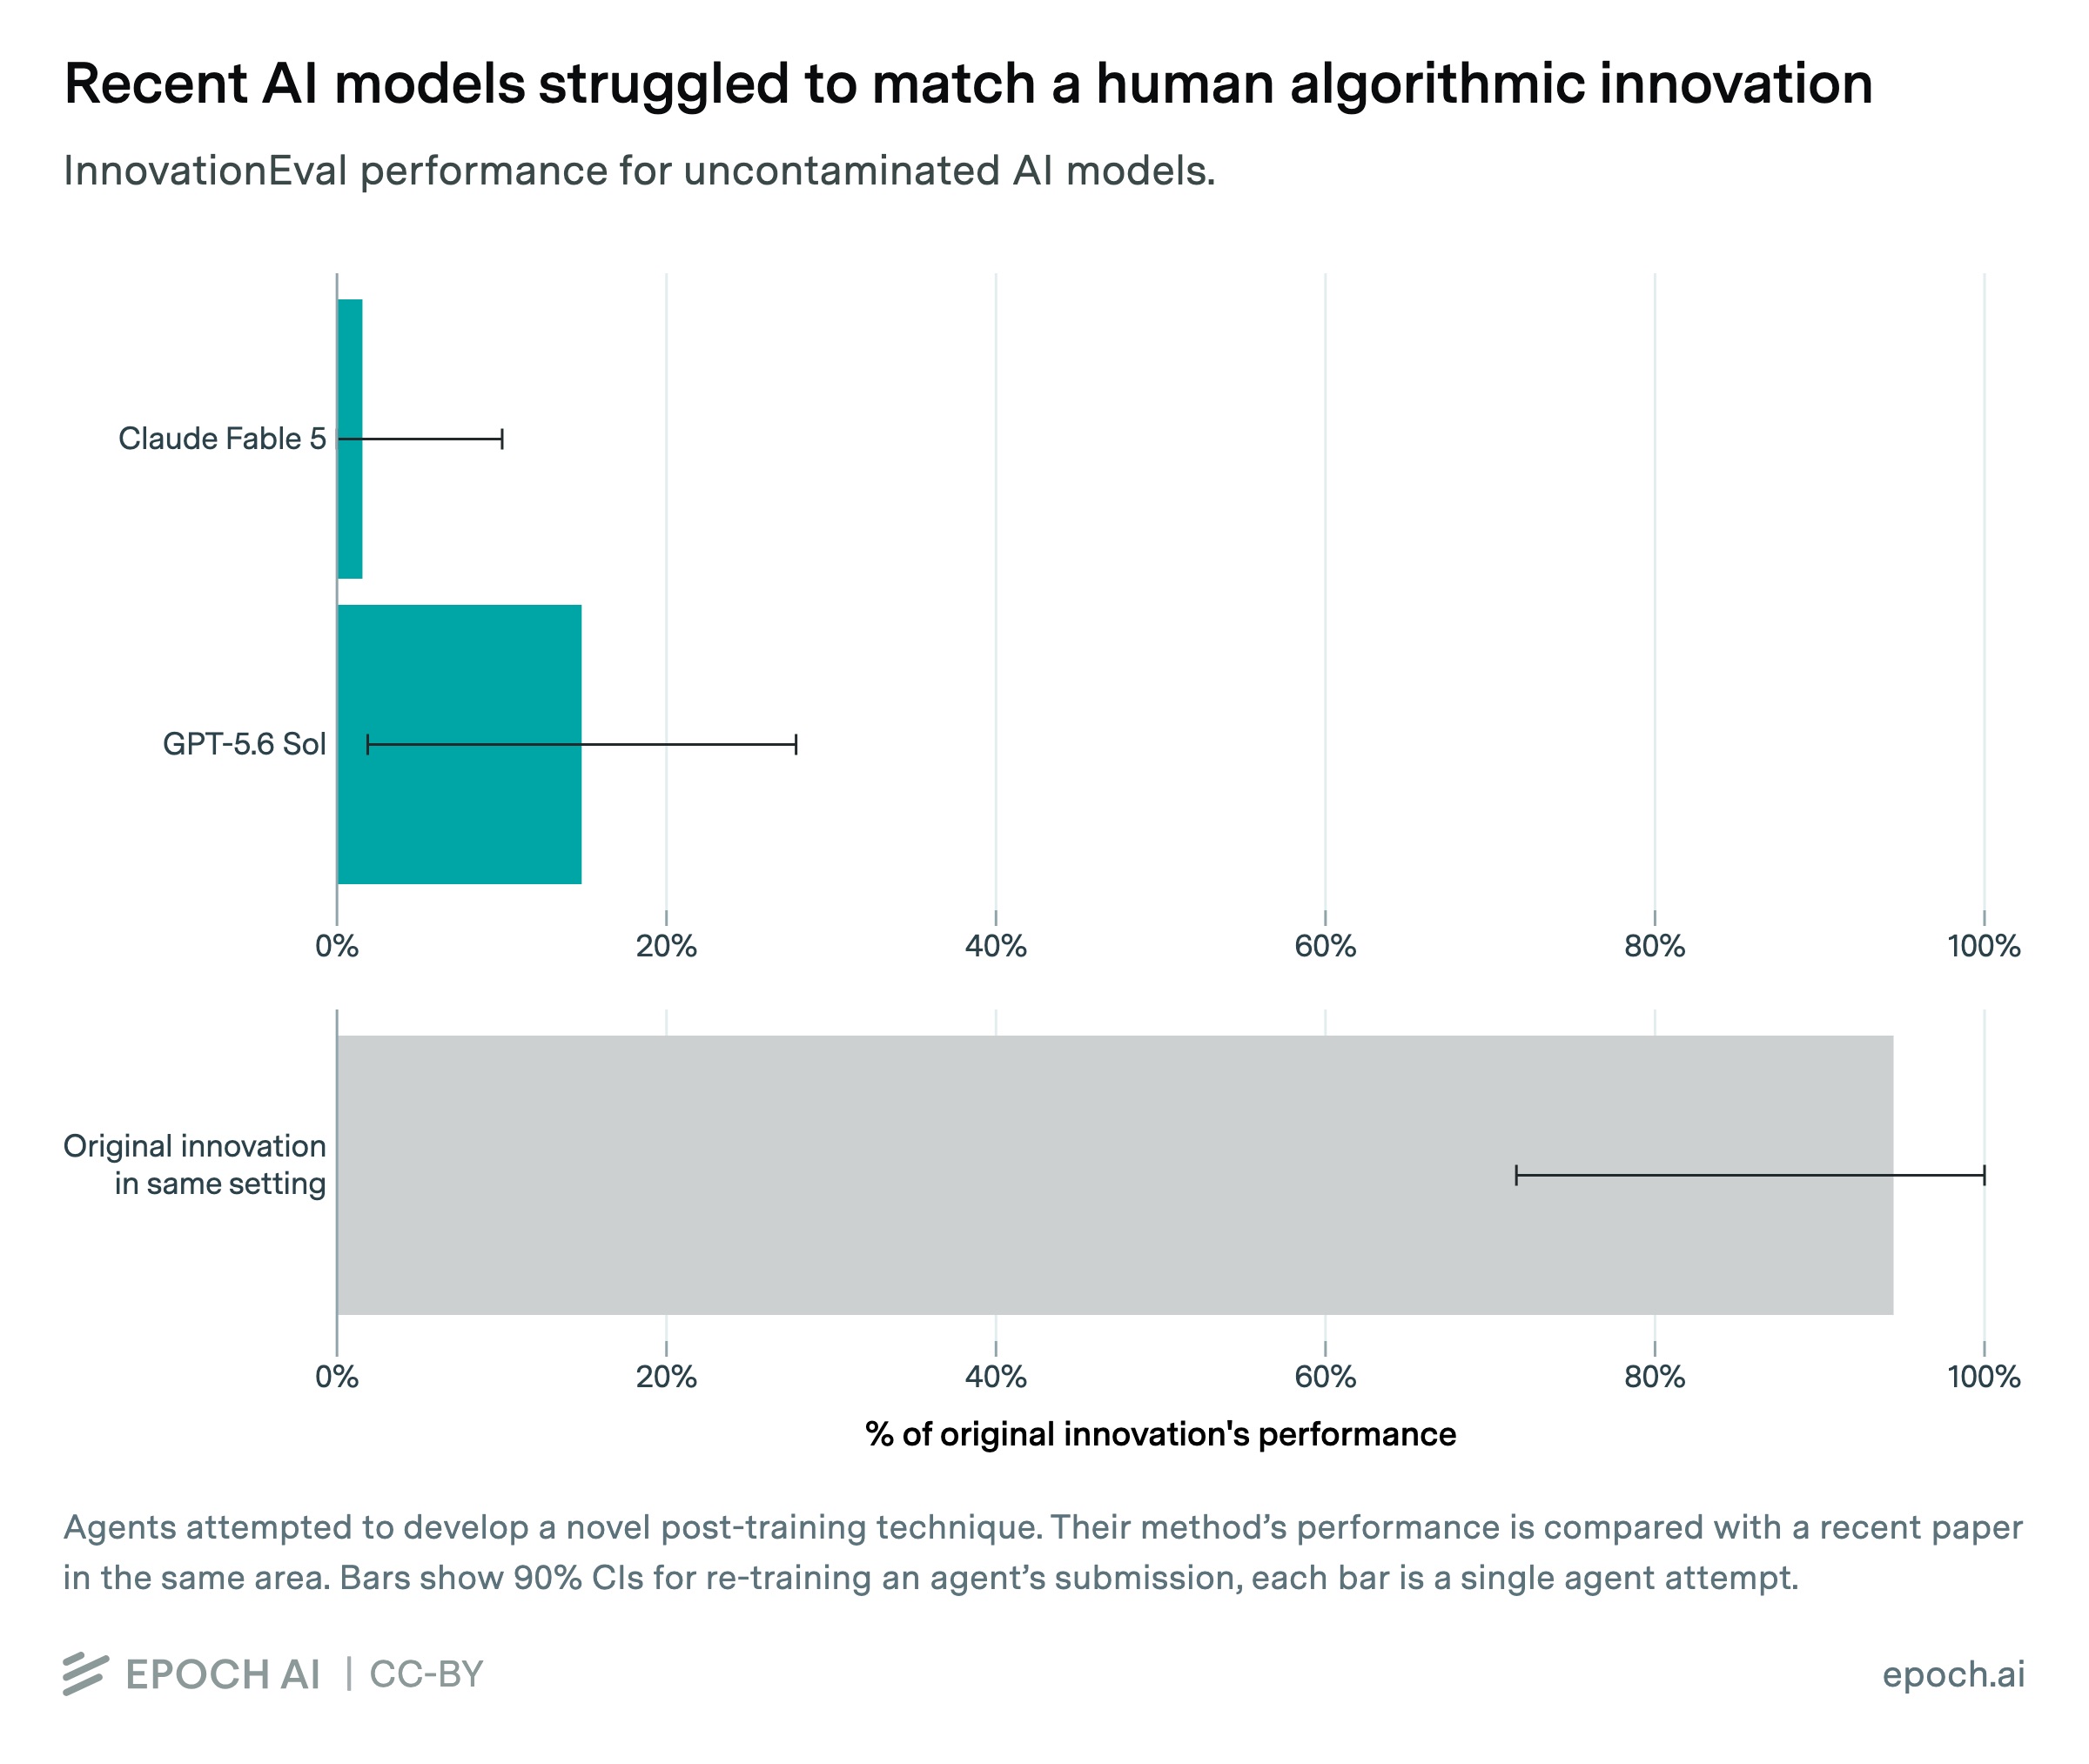
InnovationEval asks agents to devise and test a new model-training technique against a human-developed reference. With large GPU budgets, the two main models failed to match the reference: one made limited improvements using an existing idea, while the other's apparent gains failed scope review. Newer models already knew the reference technique.
Why it matters
The evaluation tests the innovation step behind claims of AI research automation and recursive self-improvement. Spending more on agents and experiments is different from producing a useful new research result.
What to keep in mind
The evidence covers one constrained research problem and few runs. Novelty and scope require human judgment; compute budgets may still matter. Contamination limits newer-model comparisons. The result neither rules out useful human-agent research nor forecasts future research productivity.